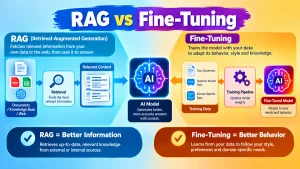
RAG vs Fine-Tuning: Which Is Better for an AI Application?technology / Sci-Tech Society / October 29, 2026 RAG vs Fine-Tuning: Which Is Better for an AI Application? Read More »
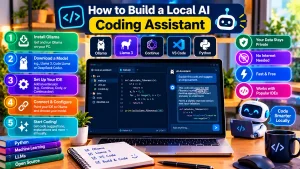
How to Build a Local AI Coding Assistant with Ollama, VS Code & Continuetechnology / Sci-Tech Society / September 24, 2026 How to Build a Local AI Coding Assistant with Ollama, VS Code & Continue Read More »
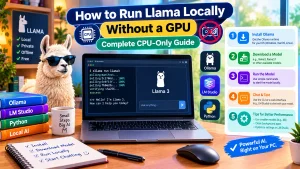
How to Run Llama Locally Without a GPU: Complete CPU-Only Guidetechnology / Sci-Tech Society / September 22, 2026 How to Run Llama Locally Without a GPU: Complete CPU-Only Guide Read More »
10 Best Local AI Models for Writing: Features & Use Casestechnology / Sci-Tech Society / September 18, 2026 10 Best Local AI Models for Writing: Features & Use Cases Read More »
What Is AI Model Quantization? 4-Bit, 8-Bit & 16-Bit Explainedtechnology / Sci-Tech Society / September 16, 2026 What Is AI Model Quantization? 4-Bit, 8-Bit & 16-Bit Explained Read More »
Local AI vs Cloud AI: What’s the Difference? Privacy, Cost & Speedtechnology / Sci-Tech Society / September 9, 2026 Local AI vs Cloud AI: What’s the Difference? Privacy, Cost & Speed Read More »
How Much RAM Do You Need for Local AI? 8GB vs 16GB vs 32GB vs 64GBtechnology / Sci-Tech Society / September 9, 2026 How Much RAM Do You Need for Local AI? 8GB vs 16GB vs 32GB vs 64GB Read More »
How to Set Up a Completely Offline AI Assistant with LM Studiotechnology / Sci-Tech Society / June 10, 2026 How to Set Up a Completely Offline AI Assistant with LM Studio Read More »
How Much RAM Do You Actually Need to Run Mistral 8B Locally?technology / Sci-Tech Society / June 10, 2026 How Much RAM Do You Actually Need to Run Mistral 8B Locally? Read More »
Ollama vs LM Studio: Which is Better for Running Llama 3 on a Mac?technology / Sci-Tech Society / June 9, 2026 Ollama vs LM Studio: Which is Better for Running Llama 3 on a Mac? Read More »